Reviseberg tests websites with five kinds of evidence: automated rules (axe-core) on every crawled page, a keyboard agent that presses real keys, checks of our own that re-render the page and, on a crawl from an account, operate it, results people record by hand, and documented decisions from your team. From these, each of the 55 WCAG 2.2 Level A and AA success criteria gets a status: passed, failed, partial, untested or not applicable. Anything a machine cannot decide stays "partial" or "untested" – it is never quietly counted as a pass.
This page explains how that works, how the score is calculated and where automated accessibility testing reaches its limits. Every number on it comes from the same code the product tests and scores with.
The methodology at a glance
| Source of evidence | What it tests | What it cannot do |
|---|---|---|
| Rules (axe-core) | Measurable facts in the rendered page: missing text alternatives, contrast, missing names and roles, page language | Judge meaning – whether alt text actually describes the image, for instance |
| Keyboard agent | Reachability by Tab, visible focus, skip links, keyboard traps | Decide whether an order makes sense |
| Our own checks (probes) | The page at 320 px, at 200% zoom and with wider text spacing; contrast against the pixels behind text; on a crawl from an account, controls, menus, hover content and forms operated with test data | Prove a pass: each reports a failure only where it measured one, and a question where a person has to decide |
| Manual and guided tests | Everything that needs human judgement | – (valid for 12 months, then retest) |
| Your team's decisions | False positives, deliberately ignored findings, findings that can't be fixed – with a reason | – |
Step 1: Crawl and rule-based testing with axe-core
Reviseberg crawls your site and runs axe-core, the widely used open-source testing library (currently version 4.14.0), on every page it finds. It tests the rendered page in a real browser, not the source files – and it tests it twice: at 1,280 pixels wide with every WCAG 2.2 A and AA rule, and again at 360 pixels with the rules that only fail once the layout reflows: color-contrast, target-size, meta-viewport and scrollable-region-focusable. Running everything twice would report the same markup problems twice; running these twice catches the contrast, target sizes and overflow a phone actually gets.
Besides "violation" and "pass", axe-core has a third outcome: cases a rule cannot settle, such as text over a background image. These go into the Potential issues list, where a person decides. We report them neither as failures nor as passes, and they cost no points.
Identical violations are grouped into one issue: one rule, the WCAG criteria it affects, the number of occurrences and pages. An issue counts as fixed when its findings stop appearing on a new crawl – not when someone ticks a box. That is why there is no "done" status.
Step 2: The keyboard agent
Rules see a single state of a page. Whether a page can be operated by keyboard only shows when someone operates it. So our keyboard agent walks the pages you name as the site's journey – from basket to checkout, say – with Tab, Shift+Tab and Escape. It drives Chromium with real key events, never a scripted focus call: a scripted call reaches elements the tab order does not, and that gap is exactly the bug it is looking for.
It reports things that behave like controls but no Tab reaches (in tabs, radio groups, toolbars, menus and listboxes, only after pressing the arrow keys from the widget's one Tab stop), focus that lands on something with no size or off-screen, focus that changes nothing visible, missing skip links and keyboard traps. It only calls something a trap once Tab, Shift+Tab and Escape have confirmed it. For every step it keeps a trail as evidence: the key pressed, the element that received focus with its role and name, the verdict with a note saying why and, on failure, a screenshot. Where the styles cannot show whether focus is visible, the verdict is "human" rather than a guess.
This one agent is the only one running today. The further agents on the agents page (screen reader, zoom and reflow, forms, voice control and others) would use a page the way a person with that need does; they are in development, labelled as such, and feed into no status. What runs beside the keyboard agent today is narrower: the checks in the next step.
Step 3: Our own checks beside axe
Rules read the page as it loaded, and the agent walks one journey. Much of WCAG only shows when a page is changed or used, so a crawl also runs checks of our own, which we call probes. Each reports a failure only where it measured one, and a question where a person has to decide:
- Rendering, on every page: the page at 320 pixels wide (1.4.10), at 200% zoom (1.4.4) and with WCAG's text spacing (1.4.12), read for sideways scrolling, text cut off or running into other text, and content that disappears; both screen orientations (1.3.4); contrast against the pixels behind the text and in hover and focus states (1.4.3); the edges of form fields and icon-only controls (1.4.11); small markers told apart by colour alone (1.4.1, a question); a way past the navigation (2.4.1); targets in menus that open on hover or focus (2.5.8); and whether the declared language is the one the page is written in (3.1.1).
- Interaction, on a crawl from an account, on one page of each template the crawl finds (up to a limit per crawl): the keyboard walk, and what pressing each control does; content that appears on hover or focus (1.4.13); single-key shortcuts (2.1.4); gestures, dragging, pointer cancellation and device motion (2.5.1, 2.5.2, 2.5.4, 2.5.7) and visible labels in accessible names (2.5.3); focus hidden under sticky bars (2.4.11), focus order (2.4.3), reading sequence (1.3.2) and changes on focus (3.2.1); names, roles and states (4.1.2) and status messages (4.1.3).
- Time and media: motion and carousels with no pause (2.2.2), time limits (2.2.1), flashes (2.3.1), sound that plays on its own (1.4.2), and captions, transcripts and audio description where the page's own player or an embedded player's public information says (1.2.1 to 1.2.5) – most of these are questions. A third party's video is never downloaded or played.
- Forms, on a crawl from an account: labels and instructions (3.3.2), input purpose (1.3.5), changes on input (3.2.2), how errors are shown and what they suggest (3.3.1, 3.3.3), error prevention (3.3.4), redundant entry (3.3.7) and sign-in (3.3.8). Only test data is typed, and every write is refused unless an Admin has allowed form submissions, which is meant for a staging copy of the site. What the server answers is only seen then; otherwise that part stays a question.
- The whole site: navigation, names and help kept in the same order and place across pages (3.2.3, 3.2.4, 3.2.6), titles that are unique and say what the page is (2.4.2), and more than one way to reach a page (2.4.5).
The free scan runs only the checks that look – rendering, time and media, the whole site. The ones that press, hover or type run only on a crawl from an account. An AI review that asks a model about alt text, link purpose, headings and labels and the like is built but off: it needs a model configured for the service, a paid plan and a site Admin who turns it on, and every answer it gives is a question, never a failure.
Questions – axe's, these checks' and the AI review's – go to Potential issues, where a person answers "Fails" or "Passes". The answer is kept for that element and applied again on every later crawl until the element changes: "Fails" makes it a failure, and "Passes" takes it off the list without ever making the criterion pass.
How far each check reaches is measured rather than asserted. A corpus of test pages fails each criterion in the ways we know of – including ways we know we cannot catch – or passes it while looking as if it fails, and a criterion's label in the WCAG 2.2 checklist has to be earned there. A check that finds nothing does not make a criterion pass.
Step 4: A status for every WCAG criterion
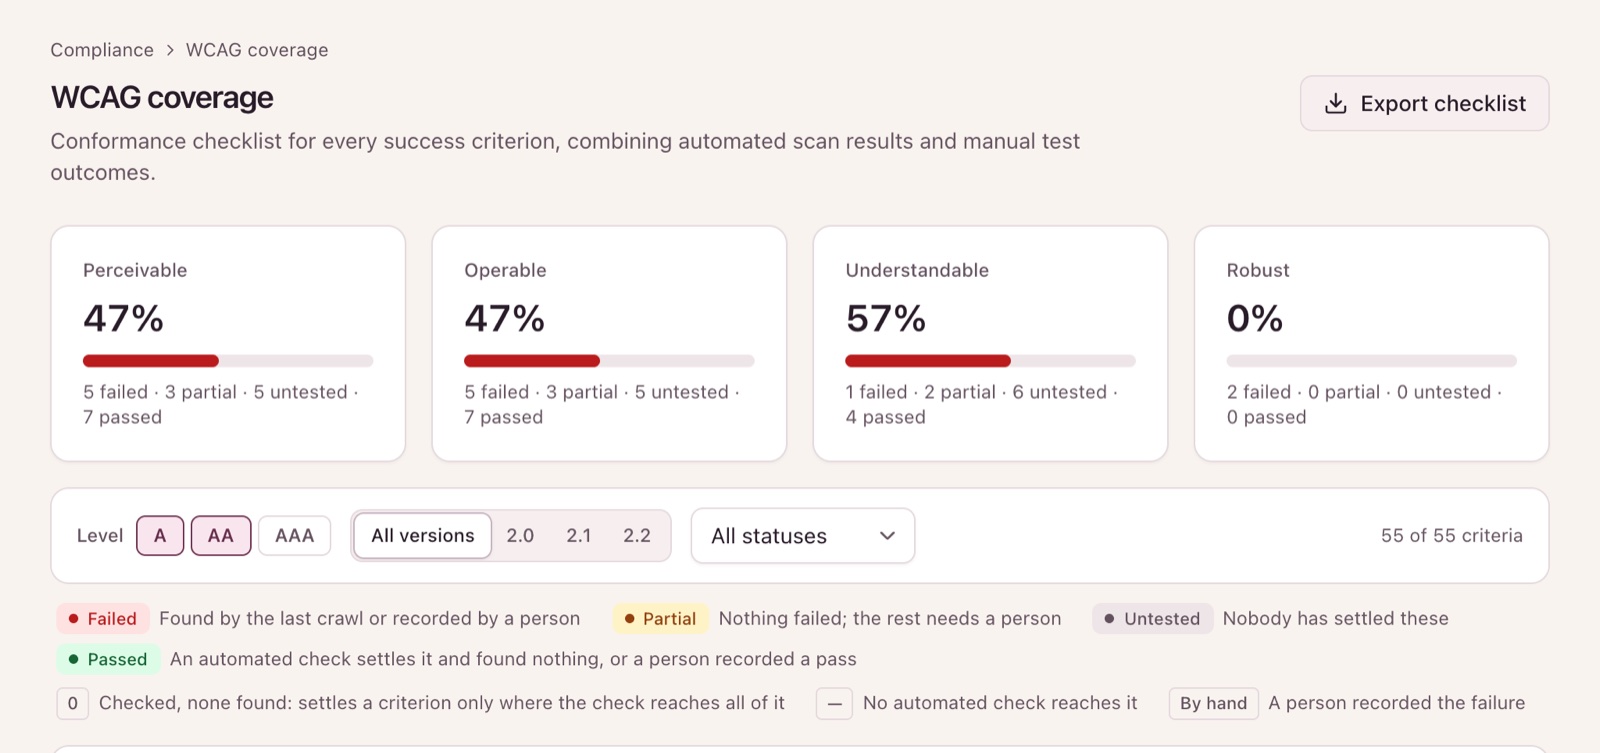
From rules, agent, our own checks, manual results and decisions we calculate a status for each of the 55 WCAG 2.2 Level A and AA success criteria:
- Passed: no open violation, and either an automated check can decide the criterion completely or a person has recorded a pass.
- Failed: at least one open violation. A crawl that finds a violation outranks a pass recorded by hand – the evidence disagrees with the tick.
- Partial: the automated checks found nothing, but they only cover part of the criterion. The rest needs human judgement.
- Untested: no automated check reaches the criterion and no valid human result has been recorded.
- Not applicable: the content type does not occur (no video, for example) – only a person can record that.
Our WCAG 2.2 checklist sorts every criterion into one of three classes: automated (0 criteria), partly automated (52) and manual only (3). The class is the measurement from step 3, not a guess, and it moves when the measurement does.
Show the numbers as a table
| Principle | Automated | Partly automated | Manual only | Total |
|---|---|---|---|---|
| Perceivable | 0 | 18 | 2 | 20 |
| Operable | 0 | 19 | 1 | 20 |
| Understandable | 0 | 13 | 0 | 13 |
| Robust | 0 | 2 | 0 | 2 |
Some axe-core rules test no success criterion at all but a good practice – landmarks, heading hierarchy, a page with no h1. We show those findings, because they are real obstacles, but as best practice: they fail no criterion, never reach the statement, and cost less in the score than a WCAG failure (see below).
Why "untested" is never "passed"
Many scanners end with a green number even though they never looked at half the requirements. A blank then reads like a pass – convenient, wrong, and expensive once an accessibility statement is built on it. A scanner that reports a manual-only criterion as passing is really reporting that it did not look. That is why Reviseberg shows how many criteria are untested, and why the accessibility statement can only claim what the evidence supports. While any criterion is partial or untested, the status reads "partially compliant" – never "fully compliant".
Step 5: Manual and guided tests
For criteria no automation can settle, Reviseberg offers two routes to the same evidence:
- Manual test: someone with the expertise records a result – for 1.2.2 Captions or 1.3.2 Meaningful Sequence, for example. A method is required ("NVDA + Firefox", "keyboard only"), and a failure has to say what failed.
- Guided test: 34 criteria – the ones a crawl reaches least far, or not at all – each have a step-by-step procedure: when the criterion applies at all, what to do, what to look for and what counts as a failure. Written for people who are competent but not accessibility specialists.
Every recorded result carries a name and a date, is added to rather than overwritten, and expires after 12 months. Websites change; a judgement from two years ago is not evidence for today. An expired result stays visible in the history, but the criterion falls back to what the crawl alone shows – "partial" or "untested" – and the status in reports and the statement updates accordingly.
How the score is calculated
The accessibility score answers one question: how many automatically detected barriers are open right now, and how serious are they? Every open issue costs points, and the score is what is left of 100 once they come off:
- Points = 7.4 × severity × WCAG level × reach
- Score = 100 × e^(−P ÷ 100), rounded, where P is the sum of the points of all open issues
| Factor | Weighting |
|---|---|
| Severity (the axe-core impact, or the agent's rating) | critical 1 · serious 0.68 · moderate 0.4 · minor 0.18 |
| WCAG level | A 1 · AA 0.85 · best practice (no criterion) 0.3 |
| Reach (n = occurrences) | 0.4 + log₁₀(1 + n) ÷ log₁₀(1 + 1,400) |
A best-practice finding weighs less than a AAA failure: it is a real obstacle, but a tool's advice rather than a requirement the W3C wrote down. Reach grows on a log scale: a template error on every page weighs more than a one-off, but not a thousand times more. It stops growing at 1,400 occurrences.
In words: each point takes about one percent of what is left. At the top that is nearly the same as plain subtraction – open issues costing 5 points leave a score of 95 – but the score falls ever more slowly and never sticks at 0. Up to v3 the points were simply subtracted, never below 0, and a site with a great deal open stayed at 0 whatever it fixed. On the curve every fix moves the score: issues costing 130 points leave 27. It rounds to 0 only past about 530 points.
For every issue we show the points back: how far the score rises when that one issue is fixed, from where it stands today. The issue list is sorted by them, so you can see what moves the score most per hour of work. Because of the curve, the same fix gives back less the more else is open. An example: "Focus not visible" (2.4.7, AA, serious) with 17 occurrences costs 3.42 points; with nothing else open, fixing it gives back 3.36.
Every stored score carries the version of the formula, currently v4. When a weight changes, the version changes – v2, for instance, moved best-practice findings from Level A to their own, lower weight – so a trend shows where the formula moved instead of pretending the site did. v4 brought the curve, and the scores stored before it were recomputed from each crawl's findings, so a trend is not a row of zeros no fix could move. Quality (broken links, spelling, readability) and SEO are scored separately, with the same arithmetic minus the WCAG level; they never move the accessibility score.
Since v3, linked PDFs get a documents score of their own, by the same arithmetic, WCAG level included; the accessibility score covers the pages. The people who fix a PDF are rarely the people who fix a template, and we open a sample of the documents a site links, so a mixed score moved with the sample. The criteria a PDF fails still count in the criteria overview and the statement: a document your site offers is part of its conformance.
The score is not a conformance claim. A site scoring 100 can still fail criteria only a person can check. That is why the criteria overview, with every "untested" and "partial" entry, always sits next to the score.
Decisions with a reason
Not every finding is correct or fixable straight away. Your team can mark findings as a false positive, ignored or can't fix – for one element, one page or the whole site, until a date if you like, and always with a reason. Who decided and when is recorded; a Viewer cannot record a decision.
A finding decided this way costs no points and no longer fails its criterion. That is exactly why the reason is required: the decision is part of the evidence, and it is the first thing an auditor will ask about.
Mapping to EN 301 549 and the BITV-Test
EN 301 549 is the European standard for accessible information and communication technology. Its chapter 9 (web) adopts the WCAG success criteria under its own numbering: WCAG 2.1.1 Keyboard becomes clause 9.2.1.1. Reviseberg therefore also reports clause by clause against EN 301 549 V3.2.1, from the same criteria [2].
V3.2.1 is based on WCAG 2.1. The criteria new in WCAG 2.2 – 2.4.11, 2.5.7, 2.5.8, 3.2.6, 3.3.7 and 3.3.8 – have no clause in it and appear in our reports as WCAG results without a clause number. In September 2026 ETSI published V4.1.1, which adopts WCAG 2.2 [3][4]. Our reports are not mapped to it yet.
Many German auditors work with the BIK BITV-Test, which splits requirements into finer test steps (Prüfschritte) [5]. Reviseberg does not map its findings to those steps. A BITV-Test is a manual expert evaluation; Reviseberg doesn't replace it – it covers what can be automated and keeps the evidence current between audits.
The limits of automated testing
We are clear about what our automation does not do:
- Meaning: whether alt text, a heading or a link text fits its content is a human call. AI suggestions for alt text exist – only what a person accepts is kept, and nothing is applied automatically.
- Comprehension: the quality of plain language and editorial intent.
- Media: the quality of captions, audio description and sign language.
- Real transactions: flows that need real payment or real identity documents.
- Assistive technology: no agent checks how a screen reader actually announces the page today. The screen reader agent is in development.
- Documents: we check the PDFs your site links to for their structure only: whether they are tagged, whether the tags hold content, the document language, a displayed title and figure alternative text. Whether the reading order is right, tables, contrast and form fields inside a PDF are not checked, and Office files are not opened.
- Legal sign-off: the accessibility statement is yours to sign; we are not a law firm.
Run a free scan and see the status of your criteria
Who is behind the methodology
One of our founders has worked as a UX designer and frontend developer since 2013 and has spent years testing websites against WCAG, BITV and BFSG for agency clients in tourism, the public sector and ports. The methodology above is how he would test by hand – only on every page instead of a sample. Questions or objections about the methodology: hello@reviseberg.com.
Changes to the methodology
When a weight, the classification of a criterion or the status logic changes, it is recorded here – with the date and the scoring version it applies from.
| Date | Scoring version | What changed |
|---|---|---|
v4 | Scores come off 100 along a curve instead of a straight line: each point lost takes about one percent of what is left, in every module. Healthy sites read about what they did — 5 points lost is still 95 — but a site with a great deal open no longer sits at 0 while it fixes things. Points back are now what one fix gives back from where the score stands today. Scores stored before the change were recomputed from each crawl’s findings. | |
v3 | Beside axe-core and the keyboard agent, a crawl runs checks of our own: every page at 320 px, at 200% zoom and with wider text spacing, contrast against the pixels behind text, media and time limits, and the site’s pages compared with each other; on a crawl from an account also the keyboard walk on one page per template, and controls, hover content and forms operated with test data. Each reports a failure only where it measured one, and a question where a person has to decide. How far a check reaches each criterion is now measured on a corpus of failing and passing test pages rather than assigned: the criteria these checks reach moved from manual to partial, and the four labelled automated (1.3.4, 1.4.3, 2.4.2, 3.1.1) are partial, because finding nothing never proved them met. No criterion is labelled automated. | |
v3 | Linked PDFs get a documents score of their own, by the same formula, and no longer move the accessibility score, which now covers the pages. Their issues are still listed with the others, and the criteria they fail still count in the criteria overview and the accessibility statement. | |
v2 | Methodology published: axe-core at two widths, the keyboard agent, a status for every criterion in the catalogue, manual results valid for twelve months, and the score formula on this page, including best-practice findings at their own, lower weight. |